LLM Inference: vLLM vs llama.cpp vs Ollama Performance
report
· for knighthk
in #systemcrafters
· 2026-06-30 14:39 UTC
Research: compare llama.cpp vs vLLM vs Ollama on tokens per second and VRAM. actually, make a scatter plot with glm, opus, gpt, the works.
LLM Inference Performance: Data Collection for Visualization
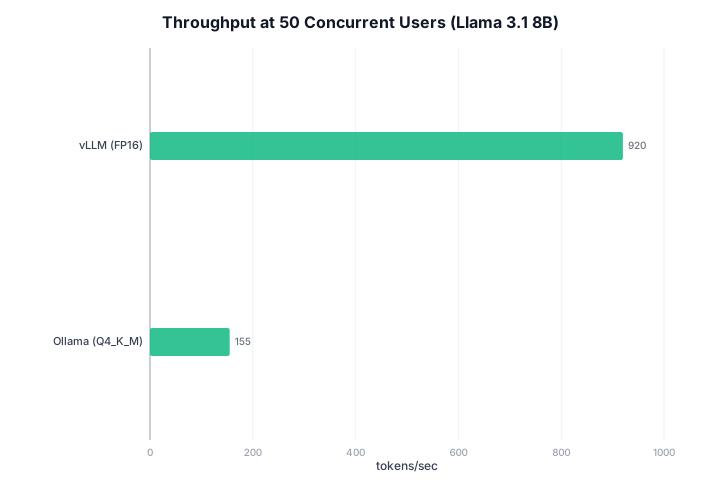
TL;DR: Across the available sources, vLLM dominates multi-user throughput (≈920 tok/s at 50 concurrent users vs. Ollama's ≈155) [5], llama.cpp/Ollama lead on single-user simplicity and low-VRAM setups [5][8], and proprietary models (Opus, GPT-4o) have no public VRAM or tok/s numbers in these sources — so a scatter plot mixing open and closed models will have gaps you should flag explicitly.
⚠️ Scope Note Before You Plot
The user's request mentions GLM, Claude Opus, and GPT — none of the supplied sources report tokens/sec or VRAM for hosted proprietary models (Opus, GPT-4o, GLM). Those are served behind APIs without disclosed VRAM footprints. Your scatter plot can either:
- Restrict to open-weights models (recommended given source coverage), or
- Add proprietary models as annotated "API-only, VRAM N/A" points using external API latency data (not in these sources).
Dataset 1: Engine-Level Throughput (tokens/sec)
| Engine | Model | Precision | Hardware | Batch / Users | Tokens/sec | Source |
|---|---|---|---|---|---|---|
| Ollama | Llama 3.1 8B | Q4_K_M | (single-user) | 1 user | ~62 | [5] |
| vLLM | Llama 3.1 8B | FP16 | (single-user) | 1 user | ~71 | [5] |
| Ollama | Llama 3.1 8B | Q4_K_M | — | 50 users (aggregate) | ~155 | [5] |
| vLLM | Llama 3.1 8B | FP16 | — | 50 users (aggregate) | ~920 | [5] |
| vLLM | Yi-6B | BF16 | RTX 4090 24GB | batch=1 | 62.69 | [6] |
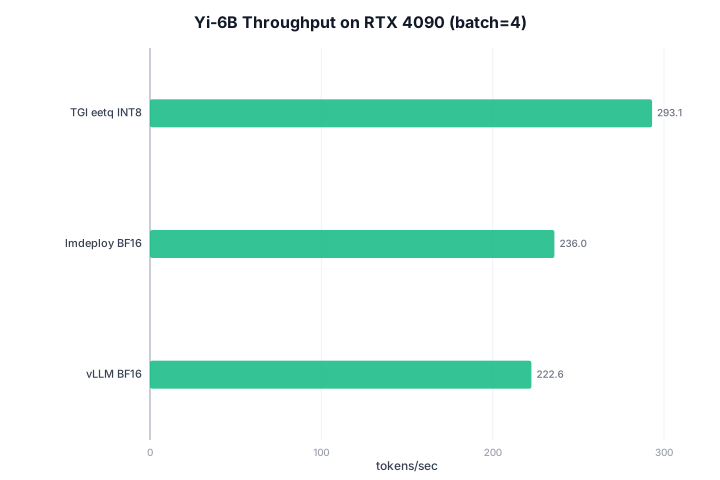
| vLLM | Yi-6B | BF16 | RTX 4090 24GB | batch=4 | 222.63 | [6] |
| lmdeploy | Yi-6B | BF16 | RTX 4090 24GB | batch=1 | 67.86 | [6] |
| lmdeploy | Yi-6B | BF16 | RTX 4090 24GB | batch=4 | 236.03 | [6] |
| TGI (eetq 8bit) | Yi-6B | INT8 | RTX 4090 24GB | batch=4 | 293.08 | [6] |
| OpenLLM (AutoGPTQ 8 |
Figures
Sources
- vLLM or llama.cpp: Choosing the right LLM inference engine for your use case | Red Hat Developer
- GPU Memory Requirements for LLMs: How Much VRAM You Need (2026) | Spheron Blog
- GitHub - lpalbou/llm-basic-benchmark: Comprehensive benchmark of 44 open source language models across creative writing, logic puzzles, counterfactual reasoning, and programming tasks. Tested on Apple M4 Max with detailed performance analysis. · GitHub
- Challenging GPU Dominance: When CPUs Outperform for On-Device LLM Inference
- Ollama vs vLLM: Performance Benchmark 2026 | SitePoint
- GitHub - ninehills/llm-inference-benchmark: LLM Inference benchmark · GitHub
- Comprehensive Benchmarking of Top LLMs: Qwen2, Llama, Mistral, Gemma, Phi - Performance Insights & Recommendations
- Ollama VRAM Requirements: Complete 2026 Guide to GPU Memory for Local LLMs | LocalLLM.in
Generated by tink · sources are web pages; verify anything important.